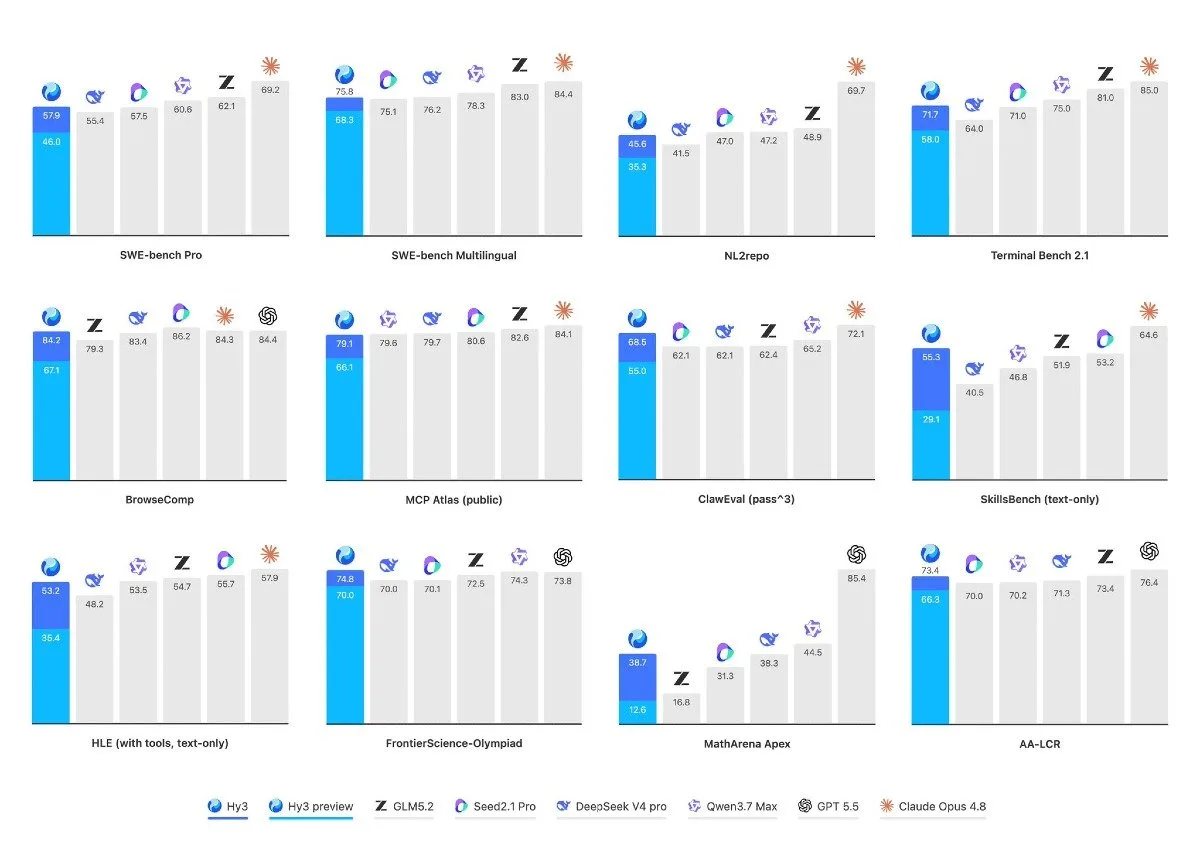
LLMs Updated October 21, 2026 Tencent Hy3: Run a 295B Flagship MoE Model on a Single GPU with GGUF and llama.cpp Learn how to run Tencent Hy3 on a single GPU using GGUF quantizations. This 295B…
LLMs Updated July 25, 2026 Bonsai 27B: The First Frontier-Class LLM That Runs on Your Phone PrismML announces Bonsai 27B, bringing frontier-class reasoning to smartphones. This model retains high performance through…
70B LLMs on 4GB VRAM — AirLLM’s Layer-by-Layer Trick That Rewrites the Rules AI Engineering Updated July 25, 2026 70B LLMs on 4GB VRAM — AirLLM’s Layer-by-Layer Trick That Rewrites the Rules AirLLM enables running 70B LLMs on 4GB VRAM without quantization. This open-source library loads transformer…
 LLMs
LLMs
 LLMs