A Two-Person Lab Trained a Text-to-Image Model for $21,038, but It Cannot Draw a Word
Linum's P-JiT 21K is a 2B pixel-space text-to-image model trained for $21,038 in GPU time, with Apache 2.0 weights. It is a genuine efficiency result, but it cannot render text and has no independent benchmark.
Linum, a two-person research lab, published P-JiT 21K on 4 November: a 2.18 billion parameter text-to-image model trained for $21,038 in GPU time. The weights are on Hugging Face under Apache 2.0, and the code is on GitHub.
The run used 64 Nvidia H100 GPUs for 8,415 H100-hours at $2.50 per hour. Linum says 8,139 hours went to pretraining and 276 to post-training, with restarts included. The model saw 610 million samples at 512 pixels and another 50 million at 1024 pixels.
The catch is in the model card. P-JiT 21K cannot render text, posters, signs or infographics, and it struggles with crowds, full-body shots and basic world knowledge. Linum calls it an experimental research artifact, not a production model.
Quick answer: P-JiT 21K is a 2.18 billion parameter, pixel-space text-to-image model from Linum, trained for $21,038 in compute on 64 H100s. The Apache 2.0 weights and code are public. It produces strong samples at roughly one megapixel, but it cannot write text and has no independent benchmark. The $21,038 covers GPU rental only, not data, salaries or the frozen text encoder.
What Linum actually built
P-JiT stands for Pyramid-JiT. It is a diffusion transformer that works in pixel space instead of squeezing images through a separate variational autoencoder. Linum argues that VAEs hit a compression ceiling and that removing one lets the diffusion model learn a latent space built for its own task.
The model splits an image into 32 by 32 patches and compresses each patch into 1,024 dimensions, a 3 to 1 reduction. Linum says that is four times more aggressive than the 16 by 16 token reduction used by models such as FLUX.2, and it cuts the attention context window by four times.
The text encoder is a frozen Qwen3.5-4B model. Linum reads layers 7, 15 and 27, concatenates the representations and projects them into the text refiner. The main trunk has 22 identical DiT blocks; extra training-only readout heads add about 0.24 billion parameters.
Training ran in two stages: 610.27 million samples at 512 pixels, then 49.97 million at 1024 pixels. Both used a global batch of 2,048 and 64 H100s across eight nodes. Post-training used Finite Difference Flow Optimization, or FDFO, with JEV-Image and human judges, and cost $690 for 276 H100-hours.
| P-JiT 21K | Detail |
|---|---|
| Architecture | Pixel-space Pyramid-JiT diffusion transformer, no VAE |
| Parameters | 2.18B at sampling; about 2.42B during training |
| Text encoder | Frozen Qwen3.5-4B, layers 7, 15 and 27 |
| Training samples | 610M at 512px, then 50M at 1024px |
| Compute | 8,415 H100-hours on 64 H100s |
| Compute cost | $21,038 at $2.50 per H100-hour |
| Output sizes | Five sizes near 1MP, from 1024×1024 to 1280×720 |
| Weights | 8.7GB in fp32, Apache 2.0 |
The $21,038 number is real, but narrow
The arithmetic checks out. Pretraining was 8,139 H100-hours at $2.50, or $20,347.50. Post-training was 276 hours at the same rate, or $690. The total is $21,037.50, which Linum rounds to $21,038.
What the number excludes matters more than what it includes. Linum describes it as compute cost, so it leaves out the data pipeline, the two researchers’ salaries and the cost of training the frozen Qwen text encoder. It also assumes a $2.50 per H100-hour rate, which depends on access to 64 H100s and a specific contract.
Linum does say restarts are included. Failed runs are usually where budget estimates quietly break. The company also published per-stage sample counts, batch size, optimizer settings and loss weights, so the claim can be audited rather than taken on trust. The result is a genuine efficiency story, not a claim that anyone can train a frontier image model for $21,000.
The samples look good, the evidence is thin
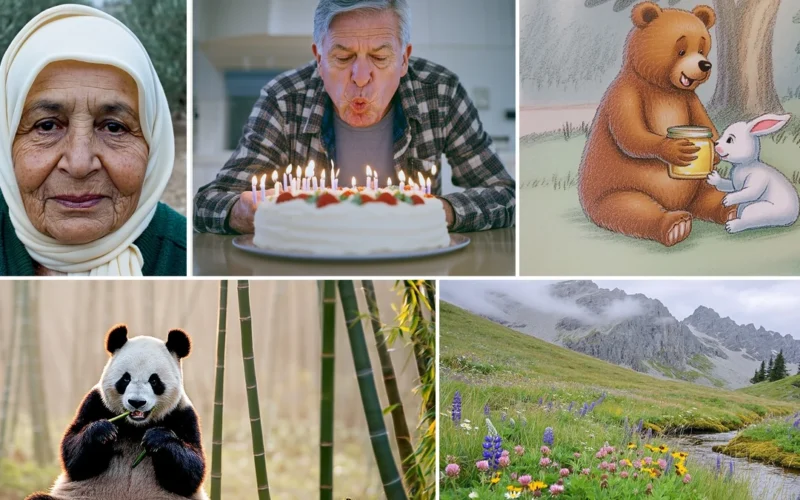
The release page shows 249 samples, with prompts and seeds. The images are often strong: a portrait with soft light, a children’s book illustration, a panda in bamboo, an alpine meadow. They are also curated by the people who built the model.
There is no FID score, no CLIP score, no GenEval result and no human preference study in the release. Linum does not compare P-JiT 21K with FLUX.2, Stable Diffusion 3.5, Qwen-Image or any other production image model. The word “decent” in the Hacker News title is a judgment, not a benchmark. Whether the model beats an existing open model on a controlled test is unknown.
One unusual detail is the code provenance. Linum says Claude Opus 5.5 wrote the model card, the GitHub README and the code that extracts the model from its internal repository. Linum reviewed the code and says the model and training are its own. That is transparent, but buyers should read the repository. The Hacker News post had 257 points on 4 November, and the Hugging Face repository had 31 likes and 122 downloads on 6 November. Those numbers measure attention, not quality.
We’re a 2-person lab researching more efficient architectures for generative image and video.https://t.co/KWV35VifgY
Last month, we published Pyramid-JiT, a pixel-space architecture that converged 11x faster than its latent-diffusion counterpart.
Today, we're releasing a 2B… pic.twitter.com/yXt3Rr7B0L
— Linum (@LinumInc) November 4, 2026
What it cannot do
The biggest limitation is text. Linum filtered out images of rendered text on purpose because they are not useful for its animation goal. The model card warns that prompts asking for words, signs, logos, title cards or posters will not work, and the prompt upsampler returns a text_requested error instead of trying. That rules out ad creative with a headline, UI mockups, infographics, book covers, packaging and social posts with a legible call to action.
The model also struggles with full-body shots, scenes with many entities such as six cars or a crowd, interactions between several people, and world knowledge such as the six strings on a guitar or the dots on a die. Linum says a larger model, perhaps 7 billion parameters, and more post-training would likely help. It has not published that model.
Hardware is the other constraint. The weights are 8.7GB in fp32 and the text encoder is 8GB in bf16 before activations. The repository requires a CUDA GPU. Linum does not publish a minimum GPU specification, so there is no supported answer for a 24GB card or a laptop.
What it means for Indian developers
The useful part for Indian teams is the recipe, not the checkpoint. Linum has shown that a pixel-space model with aggressive token reduction can converge on a modest sample budget. A research group with access to a GPU cluster can test that idea without raising a frontier-lab budget. That is the part worth copying today.
The binding constraint is the cluster, not the dollar figure. Sixty-four H100s for 8,415 hours is not a commodity in India. Teams that rent abroad must add transfer costs and deal with the fact that training data leaves the country. The release does not mention India hosting, India pricing or a data residency option.
The Apache 2.0 licence does allow commercial use and fine-tuning, which is a real advantage over API-only image models. But the model card is explicit that this is a research checkpoint, and the licence comes with no quality guarantee. Indic prompts are also untested: the release reports no Hindi, Tamil, Bengali or other Indian language evaluation.
The practical use cases are narrow: moodboards, concept art, animation previsualization and background plates where no readable text is needed. For posters, e-commerce creative or anything with a headline, this model is the wrong tool today.
Confirmed versus not confirmed
| Claim | Status | Evidence |
|---|---|---|
| P-JiT 21K has 2.18B parameters and a 4B text encoder | Confirmed | Blog post and Hugging Face model card |
| Training cost $21,038 in GPU time | Confirmed | Blog cost table; the arithmetic checks out |
| The weights are Apache 2.0 and downloadable | Confirmed | Hugging Face licence and model files |
| Linum is a two-person lab | Confirmed | Model card and company X account |
| The model produces “decent” images | Not confirmed | Curated gallery, no independent benchmark |
| It beats FLUX.2 or Stable Diffusion 3.5 | Not confirmed | No head-to-head comparison published |
| It can replace a production image model | Not confirmed | Linum calls it a research checkpoint |
| $21,038 is the full project cost | Not confirmed | Compute only; excludes data, salaries and text encoder training |
| It can render text in images | Not confirmed | Model card says it cannot draw words or posters |
FAQ
How much did P-JiT 21K cost to train?
Linum spent $21,038 on GPU time: $20,348 for pretraining and $690 for post-training, at $2.50 per H100-hour. The run used 8,415 H100-hours on 64 H100s. The figure excludes data, salaries and the frozen text encoder.
Is P-JiT 21K really open source?
The weights are on Hugging Face under Apache 2.0, and the inference code is on GitHub. That meets the usual definition of open weights. The training data is not released, so it is not fully open source.
Can P-JiT 21K generate text in images?
No. Linum filtered text-heavy images out of training, so the model cannot render words, signs, logos or posters. Prompts that request text are rejected by the prompt upsampler rather than generating garbled letters.
Does P-JiT 21K beat FLUX or Stable Diffusion?
There is no published evidence either way. Linum did not run a head-to-head benchmark against FLUX.2, Stable Diffusion 3.5 or Qwen-Image. The release shows curated samples, not controlled comparisons. Treat quality claims as unconfirmed until independent tests appear.
Sources
Linum, Training a Text-to-Image Model for $21K, 4 November 2026.
Linum, P-JiT 21K model card, Hugging Face, created 3 November 2026, accessed 6 November 2026.
Linum, P-JiT 21K code repository, GitHub, accessed 6 November 2026.
Linum, About Linum, accessed 6 November 2026.
Hacker News, Show HN: A decent text-to-image model trained for ~$20K, 4 November 2026.
Linum, release announcement on X, 4 November 2026.
Earlier coverage: Ricursive’s 65B Ripple and the benchmark gap, Tencent’s Hy4 open-weight delay, and Deepgram’s India endpoint problem.